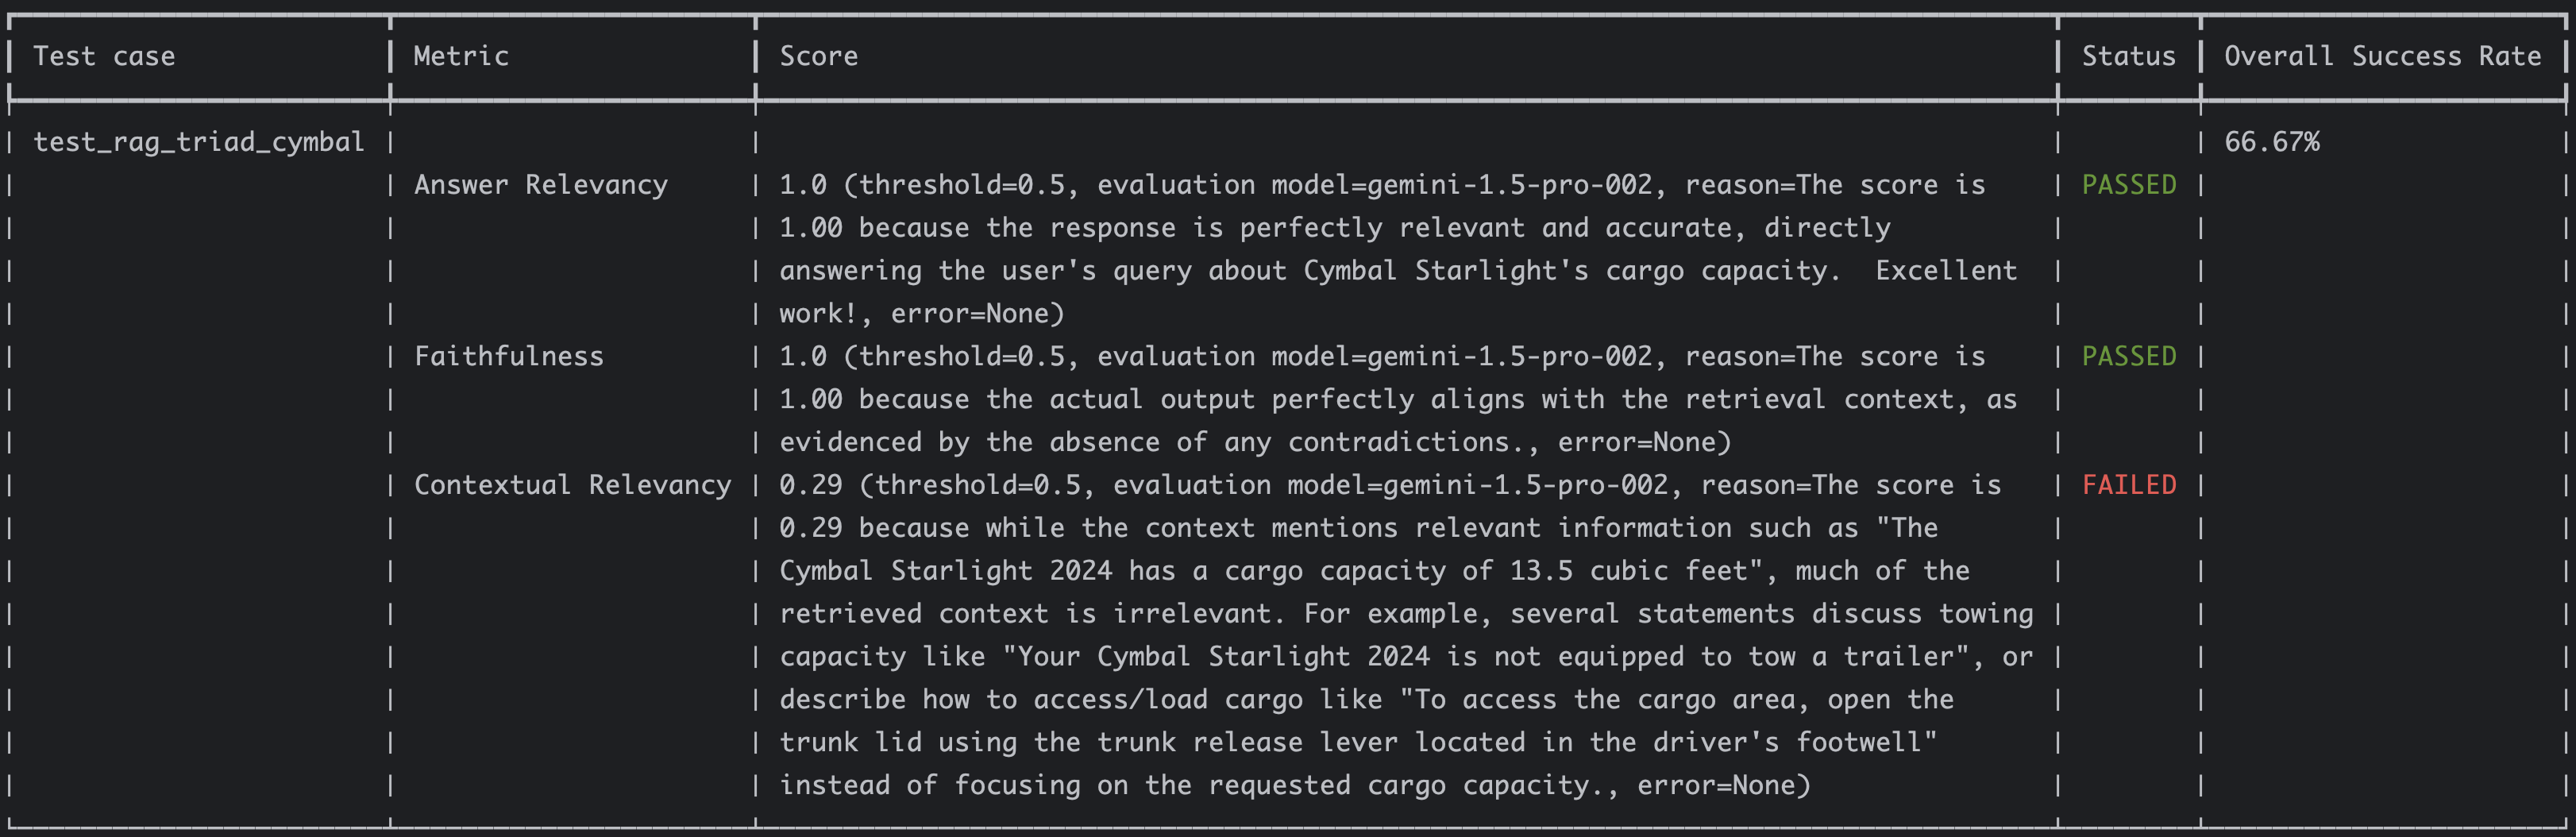
Generating content with Large Language Models (LLMs) is easy. Determining whether the generated content is good is hard. That’s why evaluating LLM outputs with metrics is crucial. Previously, I talked about DeepEval and Promptfoo as some of the tools you can use for LLM evaluation. I also talked about RAG triad metrics specifically for Retrieval Augmented Generation (RAG) evaluation for LLMs.
In the next few posts, I want to talk about a Google Cloud specific evaluation service: the Gen AI evaluation service in Vertex AI. The Gen AI evaluation service in Vertex AI lets you evaluate any generative model or application against a set of criteria or your own custom criteria.
Read More →